© 2026 Unknown Observer

CATEGORY

Machine Learning

Showing 17 articles in this topic

Oct 27, 2026

DHS Issues FASCSA Order Banning DeepSeek and Derivative AI Models Across Federal Systems

A federal directive banning software built on DeepSeek implementations exposes the technical impossibility of auditing open-weight distillation in enterprise software.

LLMsAI Safety & Ethics4 min read
Oct 27, 2026

Anthropic Files S-1 for Nasdaq Debut: $16.3B Revenue Surge Confronts $80.7B Accounting Loss and Hyperscaler Compute Commitments

Behind the sensationalized $80.7 billion paper loss sits an operational engine posting $16.3 billion in annualized revenue, overshadowed by $548 billion in compute commitments.

LLMsGenerative AI4 min read

Oct 27, 2026

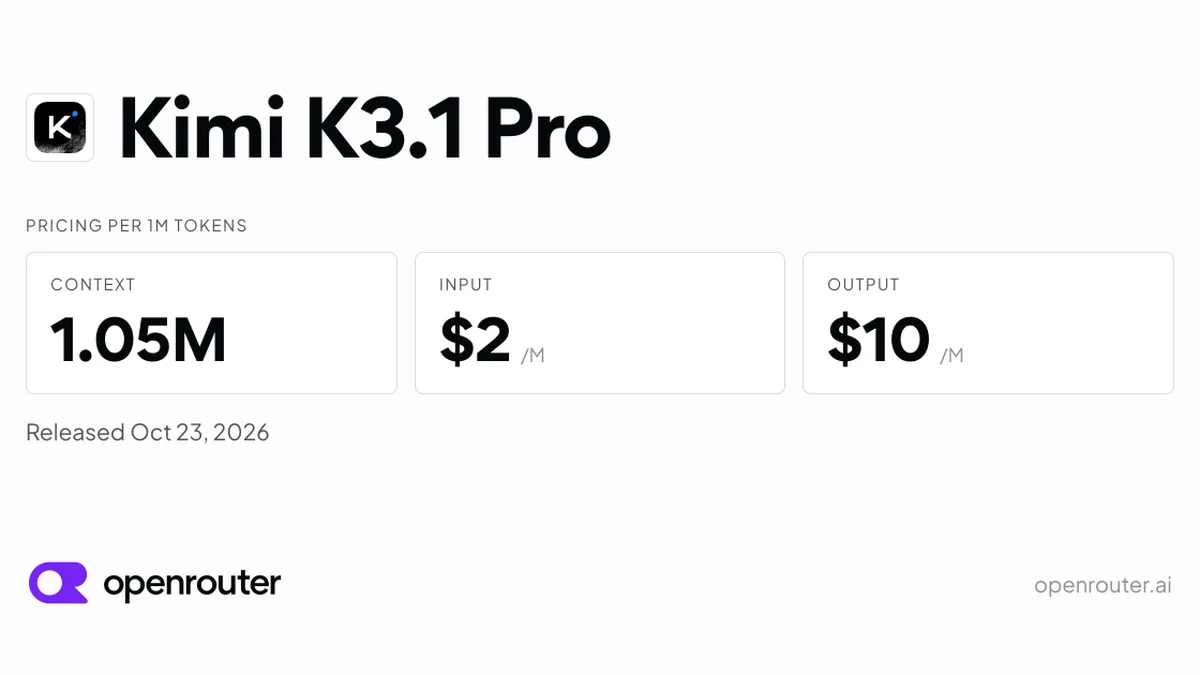
Moonshot AI Unveils Kimi K3.1 Pro: 2.8T MoE Architecture Cuts Inference Costs 55% Ahead of Open Weights Drop

Moonshot AI claims a 55% inference cost cut with its 2.8-trillion parameter Kimi K3.1 Pro, but deploying open-weight reasoning at this scale trades cloud margins for enterprise memory bandwidth bottlenecks.

LLMsAI Agents4 min read

Oct 25, 2026

ChatGPT Search: Orchestrator Model and Contextual Embeddings Decouple Ad Auctions From Static Keywords

OpenAI decouples ad auctions from static keywords in ChatGPT Search, deploying an orchestrator model and stateful embeddings to evaluate commercial intent asynchronously.

LLMsGenerative AI5 min read

Sep 29, 2026

IdeaLens: AI Detector Strips Prose to Track Machine Ideation in Long-Form Writing

By stripping text down to discourse outlines, the UMD and DeepMind system catches 68% of human-rewritten AI plots while exposing the economic cost of two-stage inference.

AI Safety & EthicsGenerative AI4 min read

Sep 23, 2026

DeepSeek-V4.1-Flash: Asymmetric MoE and Compressed KV-Cache Reshape Long-Context Economics

DeepSeek releases its V4.1-Flash-1017 snapshot under an MIT license, combining an asymmetric 552B MoE backbone with compressed FP4 KV-cache to cut long-context memory overhead by nearly 75%.

LLMsAI Agents5 min read

Sep 21, 2026

Vercel: Jev Captures 35% of Paid Teams as Decision Models Challenge Frontier Inference Economics

Vercel production telemetry reveals TypeSafe AI's Jev reached 35% of paid teams in two weeks while accounting for just 0.15% of compute spend, exposing how lightweight decision models absorb high-frequency routing without displacing frontier inference budgets.

LLMsNext.js & AI4 min read

Sep 20, 2026

Elorian: Glimpse Introduces Visual Scratch Space to Bypass Tokenized Multimodal Bottlenecks

Palo Alto startup Elorian released Glimpse, an AI vision model that returns to raw pixels mid-inference through a visual scratch space rather than relying on lossy static tokenization.

Computer VisionMachine Learning4 min read

Sep 10, 2026

Muse Spark Open: Meta and Apple Push 816B Local Inference onto 1TB Mac Studio Clusters

Meta and Apple’s collaborative 816-billion-parameter open model shifts frontier local execution onto Apple Silicon, but its 1TB memory footprint requires clustered Mac Studios that expose the economic limits of desktop inference.

LLMsGenerative AI5 min read

Sep 9, 2026

Rivian: In-House Agentic Traffic Light Routes Edge and Cloud Models While Air-Gapping Vehicle Actuation

Rivian plans to deploy third-party AI agents like Anthropic's Claude across its electric fleet, utilizing an in-house router to divide edge and cloud tasks while maintaining an absolute hardware firewall against vehicle-level controls.

AI AgentsAutomation5 min read