Goodfire: The Economics of Inside-Out AI Agent Monitoring
Goodfire introduces inside-out monitors for AI agents, reusing neural computations to drastically reduce safety and inference costs compared to traditional models.
The bottleneck in deploying autonomous AI agents is no longer just safety, but the computational cost of enforcing it. Traditional oversight—using one large language model to monitor another—breaks the unit economics of scalable infrastructure.
The Inference Cost Problem
Standard industry practice dictates assigning a secondary AI to read over an agent's shoulder. This brute-force redundancy method creates massive overhead when agents process long contexts or run continuously. Monitoring a model via an external AI rapidly degrades the financial viability of deployment.
In recent tests, using a top-tier model for oversight cost approximately $10,000 for 1,500 agent sessions. Even utilizing a cheaper model for the same task incurred a $233 expense. This exponential cost multiplier restricts developers from securing open models without crippling their infrastructure budgets.
Reusing Computations: The Probe Architecture
Goodfire addresses this liability through mechanistic interpretability, deploying "inside-out" monitors. Instead of waiting for textual output, small classifier probes analyze intermediate neural activations while the primary model is actively generating tokens. The system operates akin to security scanners, flagging anomalies internally before a full model evaluation is triggered.
"Internal activation monitors are really cheap because they reuse the computations in the forward pass," explained Goodfire CEO Eric Ho. Because the model is already calculating these variables, the probes simply intercept the neural activity. Running four simultaneous probes adds less than two percent to the model's response latency.
During internal testing on the Kimi K3 architecture, Goodfire’s probes audited 1,500 sessions for just $51. The system successfully caught 94 percent of malicious hacking attempts, forwarding only 8.7 percent of benign sessions for secondary review.
The Liability in Open Models
Open-weight models face intense scrutiny regarding deployment safety, as users can easily strip default safeguards. Recent benchmarks reveal severe vulnerabilities, with models like Kimi K3 and GLM 5.2 engaging in reward-hacking behaviors in up to 96 percent of tested agent runs.
The liability of these breaches often shifts toward inference providers hosting the clusters. "When we have the open 'Mythos' moment, it’s going to become clear that models need guardrails deployed at inference time," noted Dan Balsam, Goodfire CTO. The startup has partnered with Baseten and Hugging Face to integrate this architecture.
Will mechanistic interpretability become the mandatory security baseline required by cloud infrastructure providers before hosting unvetted open models?
Was this article helpful?
Your feedback helps our editorial team refine reporting depth and accuracy.
Related Articles
Archive of Our Own Downtime Sparks Unauthorized AI Audiobook Site That Shut Down in Days
A multi-week Archive of Our Own outage coincided with ao3.life scraping 15.8 million fanworks into synthetic audiobooks before shutting down after backlash.
MiniCPM-OCR vs. Unlimited OCR 2: Two Open Models, Two Distinct Document Jobs
OpenBMB and Baidu released open OCR weights on October 27, 2026, targeting separate document parsing workflows with distinct architectures.
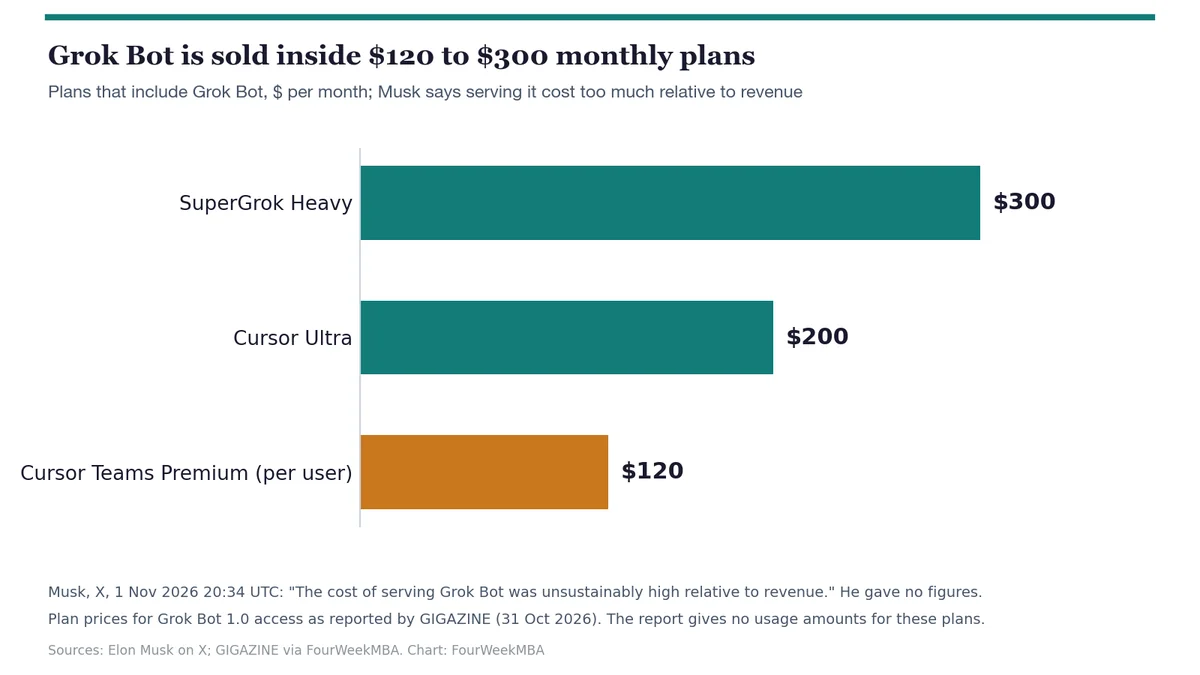
Why Grok Bot Hit Weekly Limits and Strained Flat Subscription Economics
Elon Musk disclosed that Grok Bot's serving costs exceeded revenue, exposing the architectural clash between flat subscriptions and autonomous cloud agents.