Meta Launches Muse Realtime Avatars to Turn Voice AI Into Interactive Video Characters
Meta releases Muse Realtime Avatar in the US, using Diffusion Transformers and NVIDIA inference to animate conversational AI characters in live video.
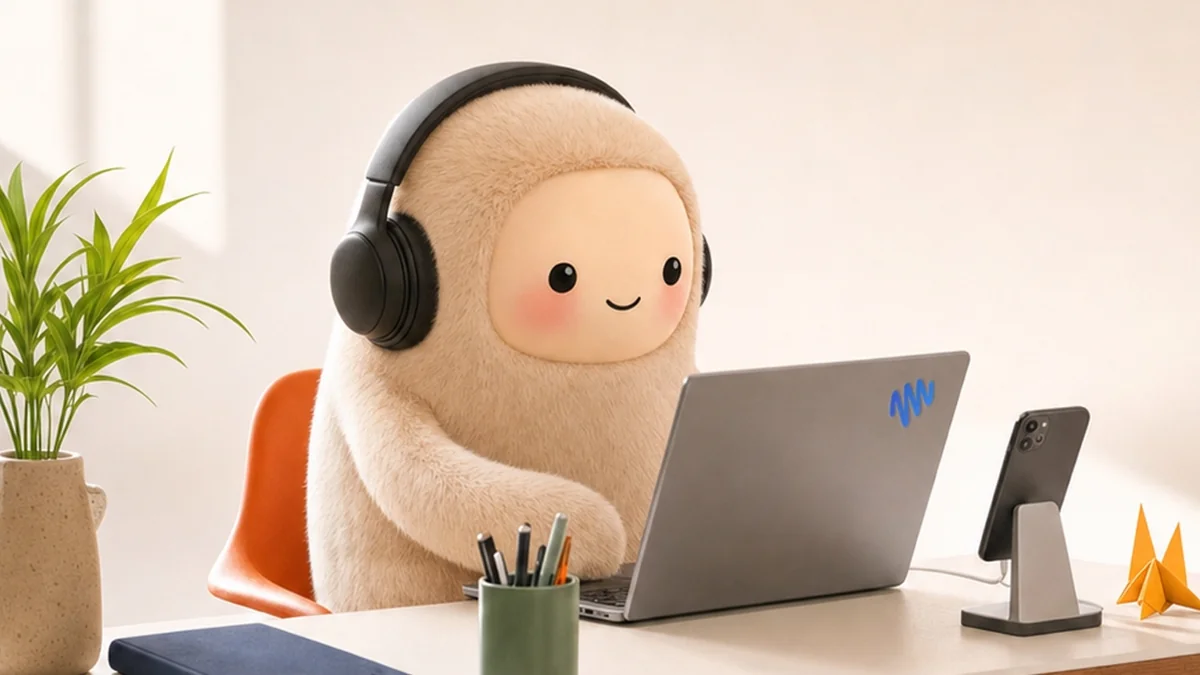
On November 5, 2026, Meta began rolling out Muse Realtime Avatar across its standalone Muse application, introducing interactive video personas to conversational sessions for users in the United States. According to Meta's official product announcement, the feature turns spoken exchanges into synchronous visual calls where animated characters respond with expressive facial movements and posture adjustments.
The release marks a deliberate pivot away from disembodied audio interfaces toward fully animated visual presence. While earlier voice assistants relied strictly on synthetic speech audio playback, this deployment pairs real-time conversational reasoning with live generative video streaming. The architectural challenge centers on sustaining low-latency video generation without imposing unsustainable hardware costs during open-ended conversations.
The technical foundation powering the system originated in research published on September 23, 2026, when Meta AI Research detailed its dual-model embodiment pipeline.
The architecture splits responsibilities between two interconnected machine learning systems named Muse Realtime Voice and Muse Realtime Avatar. The voice model processes user audio inputs to generate contextual dialogue alongside a continuous stream of specialized speech tokens. These tokens encode semantic words as well as prosodic inflections, pacing metrics, and vocal emphasis. The avatar model then consumes that structured token stream to synthesize synchronized video frames through a dedicated Diffusion Transformer backbone.
To eliminate temporal drifting between speech audio and visual output, the video pipeline operates on short causal chunks. Latent representations from the latest generated frames carry forward into subsequent generation steps, preserving spatial consistency across head tilts, gestures, and gaze directions.
The diffusion framework can ingest diverse static reference inputs, ranging from photographic headshots to full-body illustrations and stylized objects. Facial landmarks and motion vectors map onto the supplied imagery without requiring traditional geometric rigging or manual keyframing. This architectural flexibility allows the system to preserve unique character art styles while maintaining frame-to-frame stability during continuous dialogue.
Generating continuous video streams at interactive conversational speeds requires aggressive runtime optimization across server clusters.
Meta published concrete technical specifications indicating that the avatar system renders at a resolution of 448 by 768 pixels at 25 frames per second. The infrastructure delivers an initial audiovisual turn latency of approximately 870 milliseconds, calculated from the end of user speech to the arrival of the first synchronized audio and video byte. This response window accommodates network round trips while maintaining conversational tempo during active exchanges.
Sustaining that throughput required custom inference engineering, including 4-bit weight quantization and pre-compiled execution paths managed through CUDA Graphs. Reusing intermediate attention cache states prevents repetitive matrix calculations between consecutive temporal video blocks.
The economic viability of running real-time video diffusion at consumer scale prompted an expanded technical collaboration announced on October 26, 2026 between Meta and NVIDIA. The joint initiative targets software optimizations that reduce compute overhead and lower GPU memory footprints during streaming inference. Streaming neural video consumes orders of magnitude more compute capacity than generating raw text or synthesized audio tokens alone. Infrastructure architects must constantly balance frame fidelity against datacenter energy consumption to prevent operational costs from overwhelming service tier budgets.
The Muse client introduces three distinct operational layouts, allowing users to toggle between an audio-only mode, a side-by-side companion panel, and a full-screen video call layout. The interface supports instantaneous barge-in interruption, ensuring that user speech immediately halts avatar vocalization and switches video generation into an attentive listening state.
Demonstrations presented the system through calls featuring playful caricatures and domestic animals, such as an animated canine companion shared by artificial intelligence lead Alexandr Wang. However, independent testing by The Verge on November 6, 2026 illustrated the persistent tension of synthetic human likeness. The reviewer noted acute discomfort when conversing with an avatar styled after chief executive Mark Zuckerberg, describing the interaction as visually unsettling.
When synthetic human avatars display subtle misalignments between emotional tone and eye movement, user perception drops precipitously into the uncanny valley.
This psychological friction surfaces themes explored across speculative cinema such as Her and Blade Runner 2049, where emotional attachment contends with artificial boundaries. Users often tolerate abstract geometric interfaces or whimsical character animations far better than imperfect approximations of human facial anatomy. Consumer adoption will likely hinge on whether audiences prefer functional utility or emotional visual companionship in day-to-day software tools.
The current software rollout remains geographically confined to users inside the United States across mobile applications, web browsers, and macOS desktop clients. Meta has not authorized deployment across international territories, reserving global distribution pending infrastructure expansion and local compliance evaluations.
Hardware integration forms a secondary operational phase that is not yet active for consumers. The company confirmed that future roadmap milestones include porting avatar processing to Ray-Ban Meta smart glasses and the planned Muse Charm accessory. Those mobile form factors will require distributed compute offloading, streaming rendered frames over wireless networks from nearby host processors or remote edge datacenters. Local wearable silicon cannot support the thermal and battery demands of sustained 4-bit diffusion transformer execution without external offload pipelines.
Scaling embodied artificial agents requires proving that visual companionship produces tangible workflow benefits rather than novel interface complexity.
Engineering teams will measure the durability of this transition as production deployments expand beyond early consumer testing. Future iterations will test whether tightly integrated speech tokens and distilled video diffusion models can operate within affordable infrastructure budgets at global scale. The long-term viability of embodied conversational assistants depends on rigorous inference efficiency rather than cosmetic novelty alone.

Written by Adriano Nascentes
Founder & Lead AI Systems Analyst · Verified Staff
Founder and editor-in-chief of Unknown Observer. Technology researcher and software engineer investigating foundation models, autonomous agent runtimes, cognitive architectures, and frontier AI safety.
Was this article helpful?
Your feedback helps our editorial team refine reporting depth and accuracy.